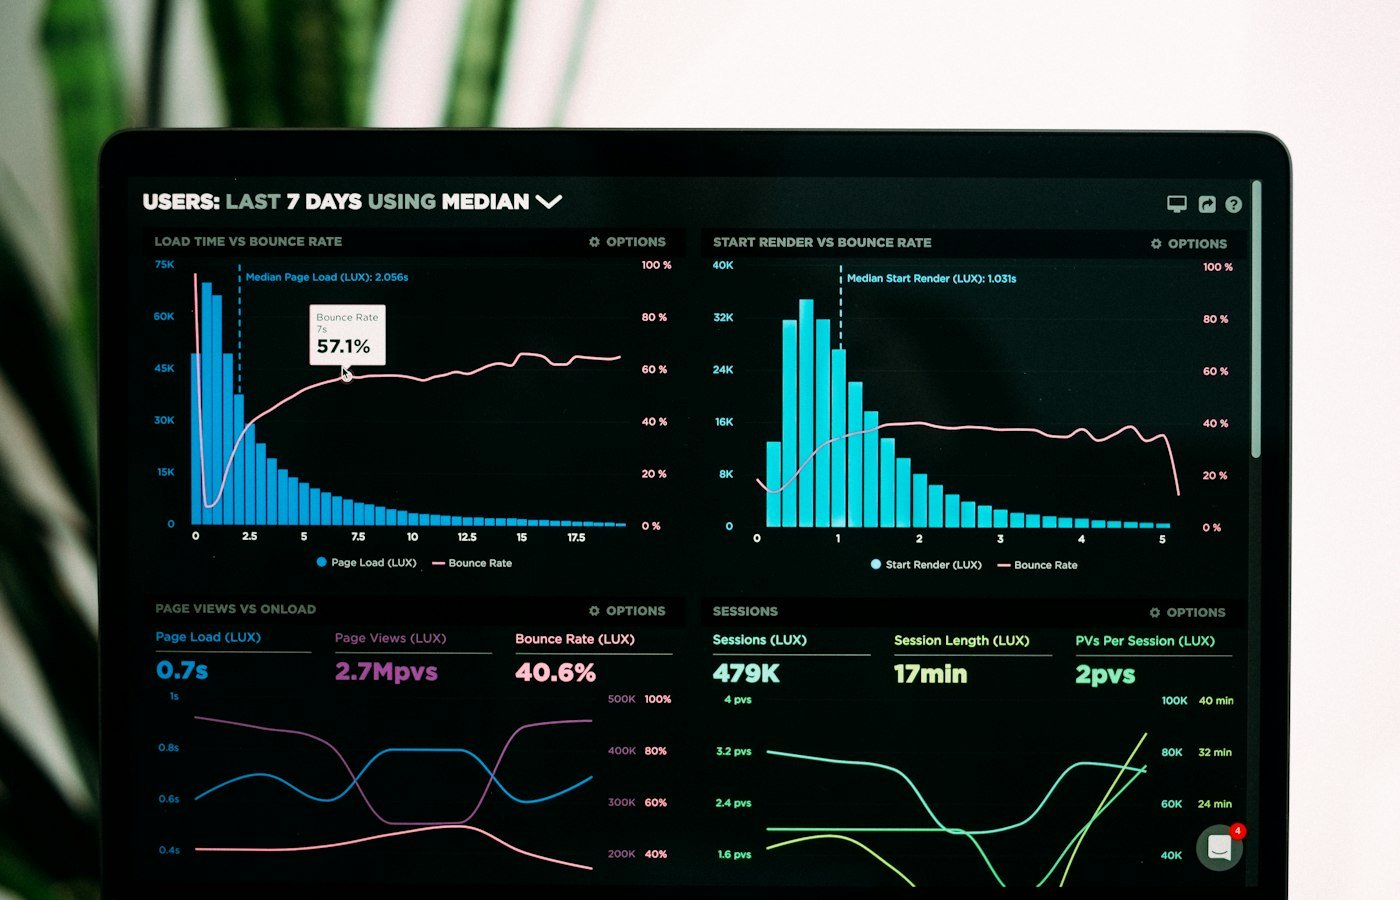
Incidents are found by users before operators. Logs, metrics, and traces live in separate tools with no shared service map. Alerts describe host noise rather than user-facing failure.
We define the signals that matter for each critical path, connect them to ownership, and set a small set of service objectives. Noise is reduced so alerts point at real failure. Performance work follows the same map: the slowest, most expensive path first. Observability is treated as part of resilient operations, not a separate dashboard project.
A picture operators can use during incidents and a baseline product teams can use for what healthy actually means.
